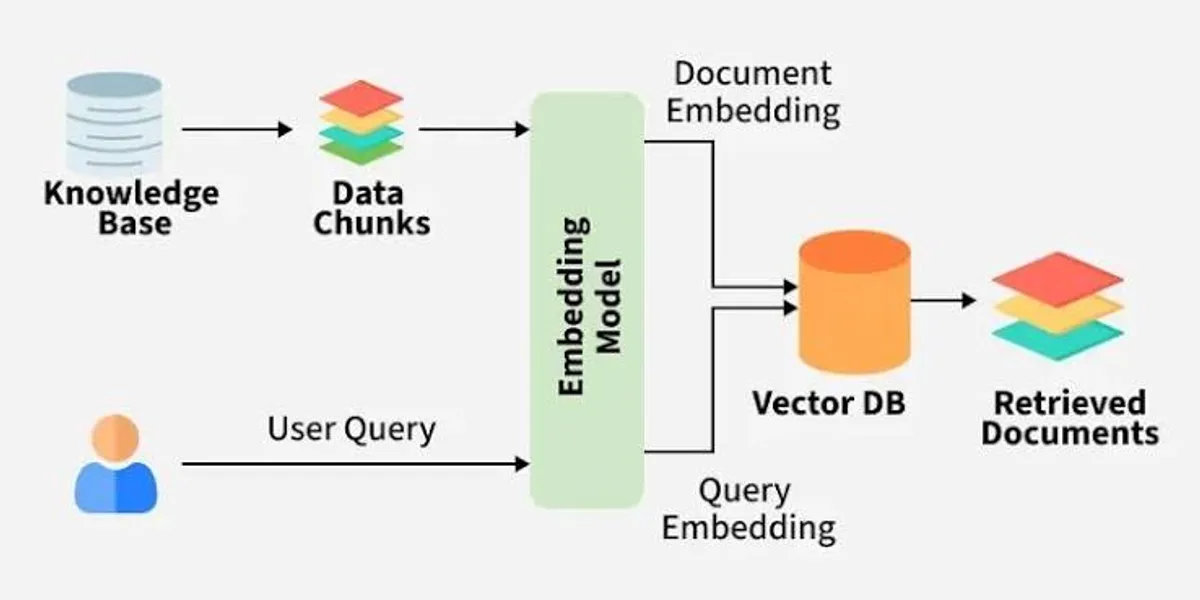
From chunking and embeddings to hybrid search, reranking, contextual retrieval, and evaluation—everything needed to build reliable RAG systems.
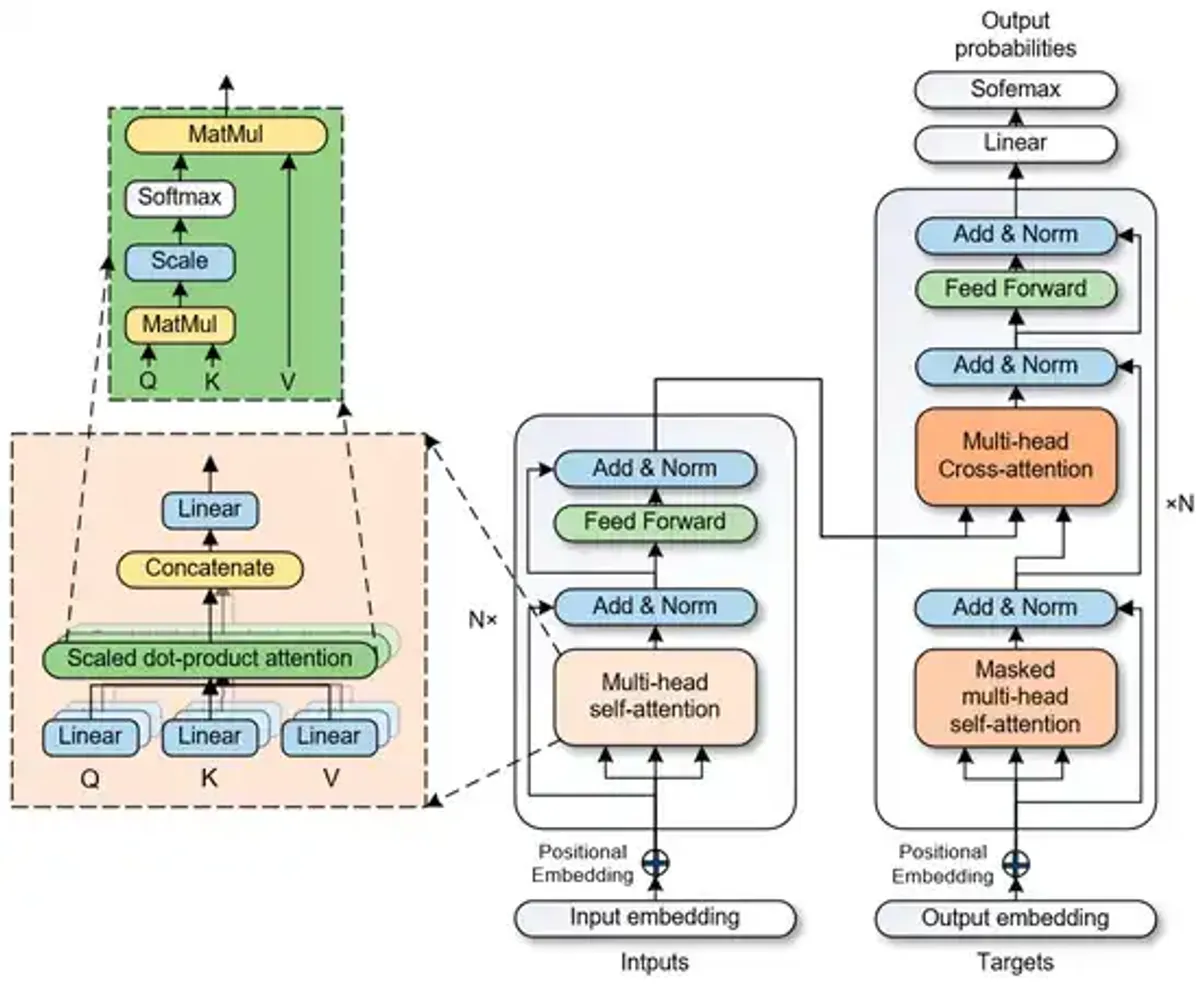
A practical introduction to how modern LLMs work, from tokens and transformers to training and inference.